
The Journey
Four Things I Didn't Believe in March
I shipped four hard-won lessons this year — about the demo-to-dependable gap, hidden failures, evaluation bars set before you're attached, and governance baked in early — that reading about never taught me, only building and failing did.
Six months ago, I thought a working prototype and something people could actually rely on were basically the same thing. They're not. Here's what taught me the difference — one shipped mistake at a time.
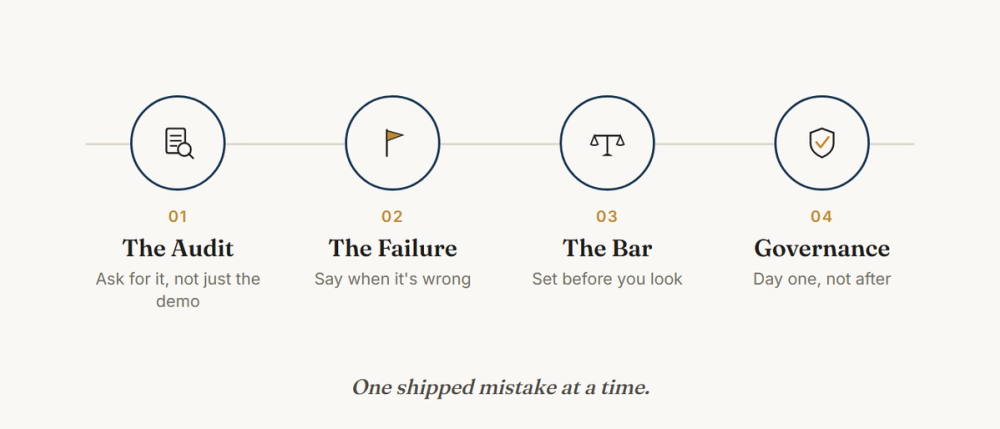
A demo can look perfect and still be broken underneath.
I built a testing tool. The main feature came together in days. The real problem showed up later: a proper audit found two deep bugs causing fifty different symptoms, and finding them took longer than building the feature. A demo never shows you that. If you're reviewing someone else's AI feature, ask for the audit — not just the demo.
If the AI fails, your app has to say so — not fake it.
One of my features had a quiet flaw: when the AI call failed, it didn't show an error. It swapped in generic pre-written text instead. It looked fine on screen. The real answer was just gone, and nothing told you that. The fix wasn't a smarter prompt — it was making the app admit when it failed instead of faking a good answer.
Decide what "good enough" means before you see the answer — not after.
I trained six versions of an AI model this year. Two of them looked good the moment I tried them. Both still failed the bar I'd written down before I saw any of their answers — so neither shipped. That's the whole rule, and any team can use it for free: write down what counts as good enough before you're attached to a specific answer.
Governance isn't paperwork you bolt on later — it's a decision you make on day one.
I added a small scoring rule to my hiring tool without thinking about it. Later I realised it was quietly shaping a ranking a real person trusted. Taking it out after the fact meant real surgery on the code. The governance question — should this rule even be here — would have taken five minutes before I wrote it. After, it took surgery.
I'd read versions of all four before — in some blog post or governance document — and nodded along without any of it sticking. Reading never taught me this. Building something, watching it break because of my own decision, with nowhere to hide — that did.
None of this is special to me.
It works the same on any team building with AI: ask for the audit, not just the demo. Check what it does when it's wrong, not just when it's right. Write down "good enough" before you see an answer. Ask the hard question before you build, not after.
By the time I looked back, I'd talked through all of this across three AI tools and well over a million words. Not a badge — it's the one habit worth stealing from all of this: get a second, independent opinion on your own work, from somewhere that didn't build it. Switching tools mid-project did that. It caught things one tool, agreeing with itself, never would have.